Gemma vs Qwen: Best Small Open Model in 2026
Gemma vs Qwen compared for local and on-device use — sizes, hardware, Apache-2.0 vs Gemma terms, verified benchmarks, and a clear verdict on which to run.
Gemma vs Qwen comes down to one trade-off: Qwen3 wins for coding, reasoning, and permissive licensing, while Gemma 3 wins for vision, audio, multilingual breadth, and the smallest phone-class footprints. Ship code or a commercial product, reach for Qwen. Need images, sound, or a sub-2GB on-device model, reach for Gemma.
TL;DR
- Verdict: For most developers running small open models locally, Qwen3 is the stronger default — better coding and reasoning scores and a clean Apache-2.0 license. Gemma 3 is the better pick when you need built-in vision, audio, or the smallest device footprint.
- Sizes and hardware: Both ship a full ladder. Qwen3 dense runs 0.6B / 1.7B / 4B / 8B / 14B / 32B; Gemma 3 runs 1B / 4B / 12B / 27B, plus Gemma 3n (E2B/E4B) built for phones from 2GB of RAM. A 27B–32B model needs roughly a 24GB GPU at 4-bit; an 8B fits an 8GB card.
- License: Qwen3 is Apache-2.0 — commercial use, no strings. Gemma uses Google's custom Gemma Terms of Use, which carry a Prohibited Use Policy and redistribution conditions. This is the single biggest practical difference.
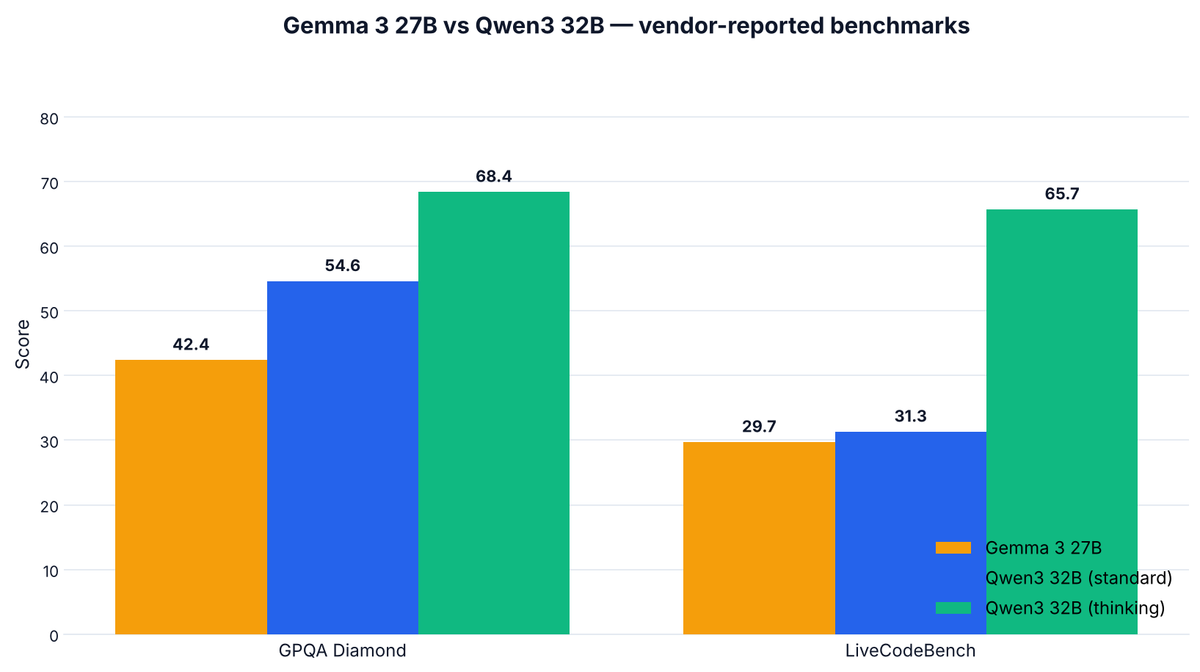
- Benchmarks: On Google's and Alibaba's own numbers, Qwen3 32B leads Gemma 3 27B on reasoning (GPQA Diamond 54.6 vs 42.4) and coding (LiveCodeBench 31.3 vs 29.7, and far higher with Qwen's thinking mode).
- Multimodality: Gemma 3 (4B and up) and Gemma 3n are natively multimodal — image, and for 3n also audio and video. Plain Qwen3 dense models are text-only; vision lives in a separate Qwen3-VL line.
Gemma vs Qwen: which is better?
There is no single winner — the honest answer is "which better for what."
Qwen3 is the stronger generalist for text work. It posts higher reasoning and coding scores at matched sizes, ships a hybrid thinking/non-thinking mode, and carries the friction-free Apache-2.0 license. If your job is code, agents, math, or anything you want to sell, Qwen is the safer default.
Gemma 3 wins on three specific fronts: native vision baked into the 4B/12B/27B models, multilingual coverage (140+ languages, per Google's Gemma 3 release notes), and true on-device reach through the mobile-first Gemma 3n line.
So "gemma vs qwen, which is better" depends entirely on whether you need pictures and phones (Gemma) or code and licensing freedom (Qwen).
The real current versions (ignore the spam)
Before the numbers, a warning. The web is full of fabricated version names — "Gemma 4," "Qwen 3.5/3.6/3.8," mystery "27B" variants. We checked primary sources, and as of October 2026 the real current open generations are Gemma 3 and Qwen3. Treat any "Gemma 4" or "Qwen3.8" spec sheet as unverified SEO filler until Google or Alibaba publishes it on an official channel.
The spec comparison
Here are the matched tiers you'll actually choose between for local use. The Runs on column is practical 4-bit guidance, not a vendor spec; every license and context figure is maker-stated, verified October 2026.
| Model (size) | Maker | License | Context | Modalities | Runs on (4-bit) | Best for |
|---|---|---|---|---|---|---|
| Gemma 3 1B | Gemma Terms | 32K | Text | Phone / CPU, <2GB | Lightweight drafting | |
| Qwen3 1.7B | Alibaba | Apache-2.0 | 32K | Text | Phone / CPU | Light text + tool calls |
| Gemma 3 4B | Gemma Terms | 128K | Text + vision | 8GB GPU / laptop | On-device vision, multilingual | |
| Qwen3 4B | Alibaba | Apache-2.0 | 32K | Text | 8GB GPU / laptop | On-device reasoning, coding |
| Gemma 3 12B | Gemma Terms | 128K | Text + vision | 12GB GPU | Vision + chat on one card | |
| Qwen3 14B | Alibaba | Apache-2.0 | 128K | Text | 12–16GB GPU | Reasoning, coding |
| Gemma 3 27B | Gemma Terms | 128K | Text + vision | 24GB GPU | Best Gemma vision + chat | |
| Qwen3 32B | Alibaba | Apache-2.0 | 128K | Text | 24GB GPU | Best dense Qwen reasoning/coding |
| Qwen3-30B-A3B | Alibaba | Apache-2.0 | 128K | Text | 24GB GPU (3B active, fast) | Fast local MoE |
Two things stand out. Gemma's 4B and up include vision; the equivalent plain Qwen3 dense models are text-only. And Qwen3-30B-A3B is a mixture-of-experts model — it loads 30B of weights but activates only 3B per token, so it runs far faster than a 32B dense model on the same card.
Gemma vs Qwen for coding
For coding, Qwen is the clear pick.
On Alibaba's reported figures, Qwen3 32B scores LiveCodeBench 31.3 in standard mode and 65.7 with thinking enabled, plus a CodeForces rating of 1977 in thinking mode, per DataLearner's Qwen3-32B benchmark page. Gemma 3 27B lands at LiveCodeBench 29.7 on Google's own Gemma 3 technical report — close in standard mode, well behind once Qwen reasons.
Qwen also ships a dedicated coder. Qwen3-Coder-30B-A3B — 30.5B total, 3.3B active, a 262K context window, Apache-2.0, per its model profile — is built for agentic coding and long repositories, and runs on a single 24GB GPU thanks to the MoE design. Gemma 3 has no coding-specialized variant.
If "gemma vs qwen for coding" is your whole question, run Qwen3-Coder-30B-A3B or Qwen3 14B/32B and don't look back.
Gemma vs Qwen for local / on-device use
This is where Gemma earns its keep.
Google built Gemma 3n specifically for phones and laptops. The E2B variant runs in about 2GB of memory and E4B in 3GB, and both are natively multimodal — text, image, audio, and video — per Google's Gemma 3n announcement. Nothing in the plain Qwen3 line is engineered that aggressively for the smallest devices or ships audio input.
For a laptop or single consumer GPU, both families are excellent and the choice flips to your task. An 8GB card comfortably runs Gemma 3 4B or Qwen3 4B; a 12GB card handles Gemma 3 12B or Qwen3 14B; a 24GB card (RTX 3090/4090 class) runs Gemma 3 27B, Qwen3 32B, or the fast Qwen3-30B-A3B.
For the best open model for local general text and coding, Qwen3 wins. For local vision or audio on modest hardware, Gemma wins. Whichever you choose, you'll likely serve it through Ollama or llama.cpp — both families are first-class citizens there.
How do the licenses compare?
This is the difference that outlives any benchmark.
Qwen3 is Apache-2.0. The official Qwen3 release states the dense and MoE models are open-weighted under Apache-2.0 — you can use, modify, redistribute, and build commercial products with no usage restrictions beyond standard attribution.
Gemma is not open-source in that sense. It ships under the custom Gemma Terms of Use, which grant broad rights but bind you to a Prohibited Use Policy and require that you pass the use restrictions downstream, notify recipients, and mark modified files, per the Gemma Terms of Use. Google also reserves the right to update the models and to restrict uses it believes violate the agreement.
For a hobby project, the difference is academic. For a company shipping a product, Apache-2.0 removes a legal review that the Gemma terms require. If licensing certainty matters, Qwen's terms are simpler. This is the same open-weight calculus we walk through in our DeepSeek vs Qwen comparison.
Gemma vs Qwen on benchmarks
Match the sizes and Qwen3 leads on reasoning and coding, on each vendor's own evaluation.
| Benchmark (as of Oct 2026) | Gemma 3 27B | Qwen3 32B (standard) | Qwen3 32B (thinking) |
|---|---|---|---|
| GPQA Diamond | 42.4 | 54.6 | 68.4 |
| LiveCodeBench | 29.7 | 31.3 | 65.7 |
| MMLU-Pro | 67.5 | — | — |
| MMMU (vision) | 64.9 | — | — |
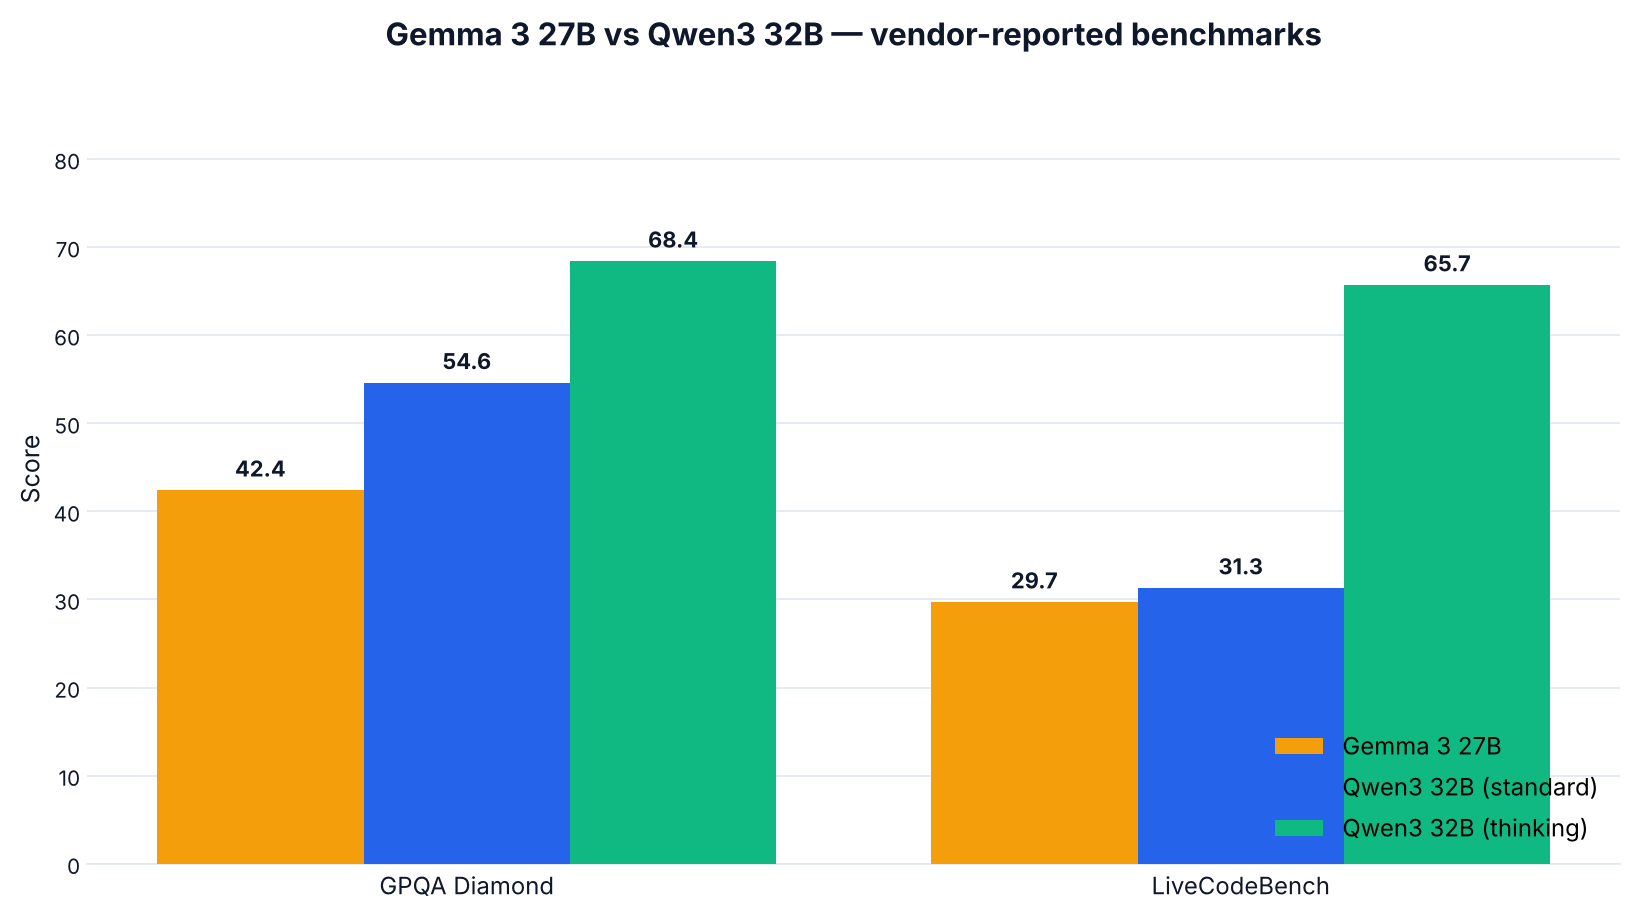
Gemma 3 27B's MMLU-Pro 67.5 and MMMU 64.9 come from Google's technical report; the Qwen3 32B figures are Alibaba's. These are self-reported by each maker and may use different settings — read them as directional, not head-to-head.
For an independent read, Artificial Analysis's Intelligence Index placed Qwen3 32B above Gemma 3 27B on its leaderboard. Note that Artificial Analysis relaunched the index as v5.0 around 27 October 2026 with a lower re-baseline, so older absolute scores are no longer comparable — use it for ranking, not for raw numbers. On "qwen vs gemma benchmark" questions, the ranking has been consistent: Qwen ahead on text reasoning and code, Gemma competitive on vision and multilingual.
Where Gemma holds ground is vision: its MMMU 64.9 is a real score on a hard multimodal benchmark, and every Gemma 3 model from 4B up can read an image out of the box. To match that in the Qwen world you step outside plain Qwen3 to the Qwen3-VL line (2B/4B/8B/32B dense plus MoE), which is a separate download.
Which should you run?
Pick by the job, not the brand.
- On-device / edge, smallest footprint: Gemma 3n E2B/E4B (2–3GB, audio + vision) — nothing in plain Qwen3 goes this small with this much multimodality.
- Local coding: Qwen3-Coder-30B-A3B or Qwen3 14B/32B — higher code scores, long context, Apache-2.0.
- Multilingual chat: Gemma 3 (140+ languages) edges it, with Qwen3 a strong second.
- Vision on a laptop: Gemma 3 4B/12B for built-in simplicity, or Qwen3-VL if you want Qwen's reasoning with images.
- Commercial product, licensing certainty: Qwen3 (Apache-2.0).
- Fine-tuning base: either, but Apache-2.0 makes Qwen3 the cleaner foundation to redistribute.
Gemma also competes head-to-head with Meta's models; if that's your real comparison, see our Qwen vs Llama breakdown.
Our take
Here's our thesis: for the developer running small open models on their own hardware in late 2026, Qwen3 is the better default, and it isn't close for text work — but Gemma 3 is the one model family you should keep installed alongside it, because it does two things Qwen's base models simply don't.
Start with what benchmarks miss, because for local use they miss a lot.
Quantization quality matters more than the headline score. A model is only as good as its 4-bit GGUF, and here both families are mature — Gemma 3 and Qwen3 both have well-behaved community quants that hold up at Q4_K_M. In our experience Qwen3's smaller sizes (4B, 8B) degrade more gracefully under aggressive quantization than most rivals, which is exactly what you want on an 8GB card. That's a practitioner observation, not a lab result, so weight it accordingly.
Tokens per second is the number you'll actually feel. This is where the Qwen3-30B-A3B MoE design is quietly brilliant: because only 3B parameters activate per token, it generates far faster than a 32B dense model while keeping most of the quality, and it still fits a 24GB card. If you're choosing one local model for responsiveness on a single GPU, that MoE is our pick over any dense 27B–32B option — Gemma included. Gemma 3 has no MoE in the small range, which is a real gap for latency-sensitive local use.
Ecosystem and tooling are a wash, which is itself notable. Both families are day-one supported in Ollama, llama.cpp, and vLLM; both have abundant fine-tunes and LoRAs. Five years ago the "open model" conversation was dominated by Llama's tooling lead. That moat is gone — you can serve either of these as easily as any model, which is why the decision comes down to capability and license rather than plumbing.
Now the license, because it's the part people under-weight. Apache-2.0 versus the Gemma Terms of Use is not a formality when you ship to customers. Qwen3's Apache-2.0 means your legal team signs off in an afternoon. The Gemma terms are permissive but conditional: a Prohibited Use Policy you must propagate downstream, redistribution notices, and Google's reserved right to restrict use. For internal tools, fine. For a product you sell or a model you redistribute, Apache-2.0 is a feature, and it tilts us toward Qwen for anything commercial. We'd call this the single most defensible reason to default to Qwen.
But Gemma's multimodality is a genuine, hard-to-replace advantage. Gemma 3n reading audio and video on a phone in 2–3GB is not something plain Qwen3 does, and Gemma 3's vision being native in the 4B model — not a separate VL download — lowers the integration cost for image tasks. If your app is multimodal and small, Gemma is the shorter path.
So, the verdict by job:
- Best for coding, agents, commercial products, fine-tuning base: Qwen3 — scores, speed (via MoE), and Apache-2.0.
- Best for on-device multimodal, audio, smallest footprint, widest languages: Gemma 3 / 3n.
- Avoid Gemma if your use is commercial and you want zero license friction, or your workload is pure code.
- Avoid plain Qwen3 if you need built-in vision or audio on a tiny device and don't want to manage a second VL model.
Our one-line recommendation: install Qwen3 as your workhorse (8B for a laptop, 14B/32B or Qwen3-30B-A3B for a 24GB GPU), and keep Gemma 3n or Gemma 3 4B around for the multimodal and multilingual jobs Qwen's base models can't touch. That combination covers nearly every local use case, costs nothing, and sidesteps the version-number spam entirely.
Frequently Asked Questions
Is Gemma better than Qwen?
Not overall. On matched sizes, Qwen3 scores higher on reasoning and coding and ships the simpler Apache-2.0 license, making it the better general-purpose local model. Gemma 3 is better for native vision, audio (via Gemma 3n), multilingual coverage, and the smallest on-device footprints. Choose by task, not by a single ranking.
Which is better for coding, Gemma or Qwen?
Qwen. Qwen3 32B beats Gemma 3 27B on LiveCodeBench even in standard mode and pulls far ahead with thinking enabled. Alibaba also ships Qwen3-Coder-30B-A3B, a coding-specialized model with a 262K-token context that runs on a single 24GB GPU. Gemma 3 has no equivalent coding-focused variant.
Can Gemma and Qwen run locally on a laptop?
Yes. Both offer small sizes for consumer hardware. Qwen3 4B or Gemma 3 4B run on an 8GB GPU or a modern laptop, and Gemma 3n E2B runs in about 2GB of RAM, even on phones. Larger 27B–32B models need roughly a 24GB GPU at 4-bit quantization. Serve them through Ollama or llama.cpp.
Is Qwen Apache-2.0 licensed?
Yes. Alibaba releases the Qwen3 dense and MoE open-weight models, and Qwen3-Coder, under Apache-2.0, which permits commercial use, modification, and redistribution. Gemma, by contrast, uses Google's custom Gemma Terms of Use with a Prohibited Use Policy and downstream conditions — permissive, but not the same as a standard open-source license.
Which is best for fine-tuning?
Either fine-tunes well and both are supported across major toolchains, but Qwen3's Apache-2.0 license makes it the cleaner base if you plan to redistribute your fine-tuned weights. Gemma can be fine-tuned too, but you must carry the Gemma Terms and Prohibited Use Policy downstream, which adds compliance overhead for a model you intend to share or sell.
Editor's note — sources
All model versions, sizes, context windows, licenses, and benchmark figures were verified against primary sources in October 2026. We excluded widely circulated but unverified names ("Gemma 4," "Qwen3.8/3.6") that appear only in SEO content, not on official channels — one Google documentation URL even served an injected "deprecated, go to gemma.ai" banner, which we disregarded.
- Gemma 3 sizes, context, multimodality, 140+ languages — Google / Hugging Face, Gemma 3 release
- Gemma 3 benchmarks (MMLU-Pro, LiveCodeBench, GPQA, MMMU) — Gemma 3 Technical Report (arXiv)
- Gemma 3n E2B/E4B, memory, audio/video — Google, Gemma 3n announcement
- Gemma custom license terms — Gemma Terms of Use
- Qwen3 lineup, Apache-2.0, context windows — Qwen3 official release
- Qwen3 32B benchmark scores — DataLearner, Qwen3-32B analysis
- Qwen3-Coder-30B-A3B specs and license — Qwen3-Coder-30B-A3B profile
- Independent ranking — Artificial Analysis, Qwen3 32B vs Gemma 3 27B